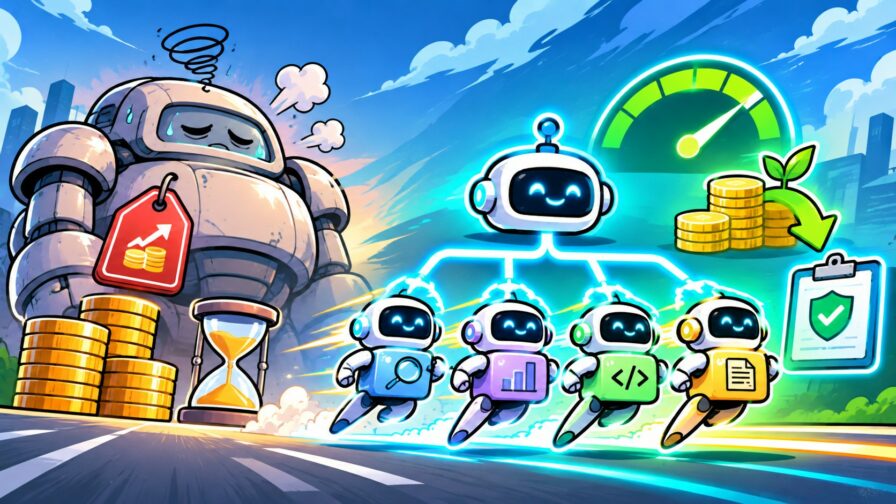
Every time a developer sends a 2 + 2 or a JSON formatting task to a proprietary 400-billion-parameter model, somewhere in the world an H100 GPU weeps and a CFO gets an over-budget notification.
At the monthly meetup hosted by ENG (Engineering) thanks to Andrea Raponi, Daniele Scasciafratte and Eugenio Petullà took apart, piece by piece, the rhetoric of the “one model to rule them all.” The message is clear: to scale AI-based products without bleeding money on compute or being crushed by European compliance requirements, we need to stop treating AI as a black box and start doing what we do best: software and systems engineering.
The Inference Paradox: Tokens, VRAM and the Hunger for KV Cache
When we call an LLM, the tokenizer breaks the text into minimal units. These units are converted into vector embeddings and processed by the GPU. This is where the first systemic bottleneck appears: the KV Cache (Key-Value Cache).
To avoid recomputing attention over all previous tokens for every single word generated in streaming, the inference engine stores the key and value tensors in the graphics card’s VRAM. The longer the context grows (up to the million tokens promised by the market), the more video memory is cannibalized by the cache, at the expense of the throughput of concurrent batches:
- If the KV Cache must live entirely in ultra-fast video memory, the ability to serve simultaneous requests collapses as soon as the number of users grows.
- If you try to move the cache to disk or secondary storage to contain costs, the latency per generated token can jump from tens of milliseconds to whole seconds.
Dev request (HTTPS)
  ──> Tokenizer (splitting into syllables/tokens)
  ──> Vector embedding generation
  ──> GPU Core (Attention processing)
  ──> KV Cache (VRAM progressively saturated to keep the context)
vLLM vs SGLang: Two Philosophies Compared
The middle layer that governs all this is the inference engine. Today the standard is played out on two platforms:
- vLLM: The historic giant, written mainly in Python and backed by hardware vendors like Nvidia and AMD. It introduced PagedAttention, an architecture that models video memory like the paged virtual memory of operating systems. It is robust, but its iteration and release speed is held back by a monolithic codebase.
- SGLang: A modern engine written in Rust, based on RadixAttention. Instead of managing the cache as a set of isolated pages, it structures shared memory as a tree/graph. In multi-turn architectures or agent flows with identical system prompts, it reuses huge portions of computation already done.
Real Compliance and Zero Data Retention: The AI Act Gives No Discounts
An enterprise application doesn’t fail only because of latency; it fails when the Legal department blocks the deployment.
Between the GDPR and the gradual rollout of the EU AI Act, relying on foreign endpoints whose Terms of Service reserve the right to retain logs for fine-tuning exposes companies to sanctions and trade secret violations. The AI Act draws a sharp distinction between those who train foundation models from scratch and those who simply serve inference on already validated open-weights models.
To guarantee full compliance, the inference infrastructure must respect a few iron pillars:
- Data Sovereignty: Servers and data centers located on national and European territory (such as the Italian nodes between Frosinone and Lombardy of Regolo/Seeweb).
- Zero Data Retention (ZDR): No persistence of prompts or completions on the infrastructure’s disks. The only traceable data is consumption metadata (tokens consumed, model called, time), needed for billing.
- Encrypted Prompt Caching: If persistent prefix caching is enabled for performance reasons, it must be encrypted with per-tenant unique keys so as not to break ZDR.
- ESG Impact & Green Energy: Inference isn’t free for the environment either; using infrastructure powered 100% by renewable sources, with visible metrics on grams of CO2 and milliwatts consumed per prompt, becomes a concrete KPI for sustainability reports.
From Cathedral to Construction Site: The Sub-Agent Architecture
Sending an entire code review or architectural analysis task to a giant “generalist” model generates unsustainable bills and watered-down answers.
The most efficient engineering approach is to split roles across specialized models coordinated asynchronously:
                     ┌──> [Sub-Agent 1: Mistral] ──> Critical analysis & bug finding
[Orchestrator: GLM] ─┼──> [Sub-Agent 2: Gemma]   ──> UI/UX & frontend code
                     └──> [Sub-Agent 3: Qwen]    ──> Specific task execution / core logic
- GLM (e.g. GLM-5) as Orchestrator: Larger models handle a wide context without losing focus, plan the activities, query the sub-agents and synthesize the results.
- Mistral (Large) as Adversarial Reviewer: A European model with strong analytical and multilingual skills, particularly inclined to spot logical flaws, edge cases and architectural violations.
- Qwen (family) as Task Executor: Chinese models with an excellent cost/token ratio in pure code execution. Given a bounded perimeter (“do this refactoring”), they execute it cleanly. They shouldn’t be used as open-ended orchestrators, though, or you risk structural hallucinations.
- Gemma (31B) as Frontend & UI/UX Specialist: An agile and effective model when it comes to laying out components, polishing interfaces (for example with Qt or HTML) and understanding visual logic.
Context Engineering: The “Linus Torvalds” Case Study on Antirez’s smallchat
An LLM released a year ago is a model that doesn’t know the latest patches, the new framework releases or your repository’s internal practices. How do you avoid the prohibitive cost of continually fine-tuning on hardware? With modular Skills injected into the context as specialized Markdown files.
An empirical experiment by Daniele Scasciafratte illustrates how it works in practice:
- A pipeline was built to process 38,000 emails written by Linus Torvalds on the Linux Kernel Mailing List over twenty years.
- From this corpus, Torvalds’ code review heuristics were extracted and synthesized into a reusable Markdown “Skill.”
- The skill was then applied to the code review of smallchat, a C++ project by Salvatore Sanfilippo (Antirez) made up of about ten files.
The benchmark results speak for themselves:
- Without the Skill: The models analyze the codebase with standard heuristics, finding superficial anomalies.
- With the Skill injected: Models like Mistral highlighted unique and precise vulnerabilities in memory management and race conditions, surpassing in depth of analysis even larger models that lacked the specific context.
- The monolithic model paradox: Huge models like GLM recorded fewer anomalies when constrained by the skill compared to more aggressive intermediate runtimes like Mistral, showing that the biggest model is not automatically the best for vertical tasks.
Developer ROI: How to Implement It From Monday
To put this strategy into practice without rewriting the entire application codebase, the starting point is decoupling:
- Adopt OpenAI compatibility: Don’t use proprietary SDKs that tie you hand and foot to a single provider. Use endpoints compatible with the standard APIs (just point the host to European inference providers like api.regolo.ai), changing only the base URL and token.
- Implement a Dynamic Router (e.g. BRICK): Don’t leave the choice of model for each query to the dev. Use open-source semantic routers that classify prompt complexity on the fly, sending trivial requests to 9B models and reserving 120B+ models for complex tasks.
- Modularize prompts into Skill Versions: Keep operating instructions in Markdown files tracked under git. This lets you update the models’ knowledge and mitigate development errors without touching a line of agent code.
Stopping the waste of tokens is not just a gesture of respect toward the company budget: it is the prerequisite for building AI software that is resilient, responsive and compliant before the next cloud provider notification arrives.
A few notes on the source text:
- I omitted the “Recommended article” block, which is a website element.
- I corrected “Seeeeb” to “Seeweb,” assuming that’s the intended provider. Please verify.
- The source has a stray “[cite: 1]” in the router section and an unclosed parenthesis in the Qwen bullet (“famiglia come Task Executor”). I removed the first and closed the second, so double-check against the original.
- The article says SGLang is written in Rust. As far as I know, it is mainly Python, so you may want to verify that claim before publishing.